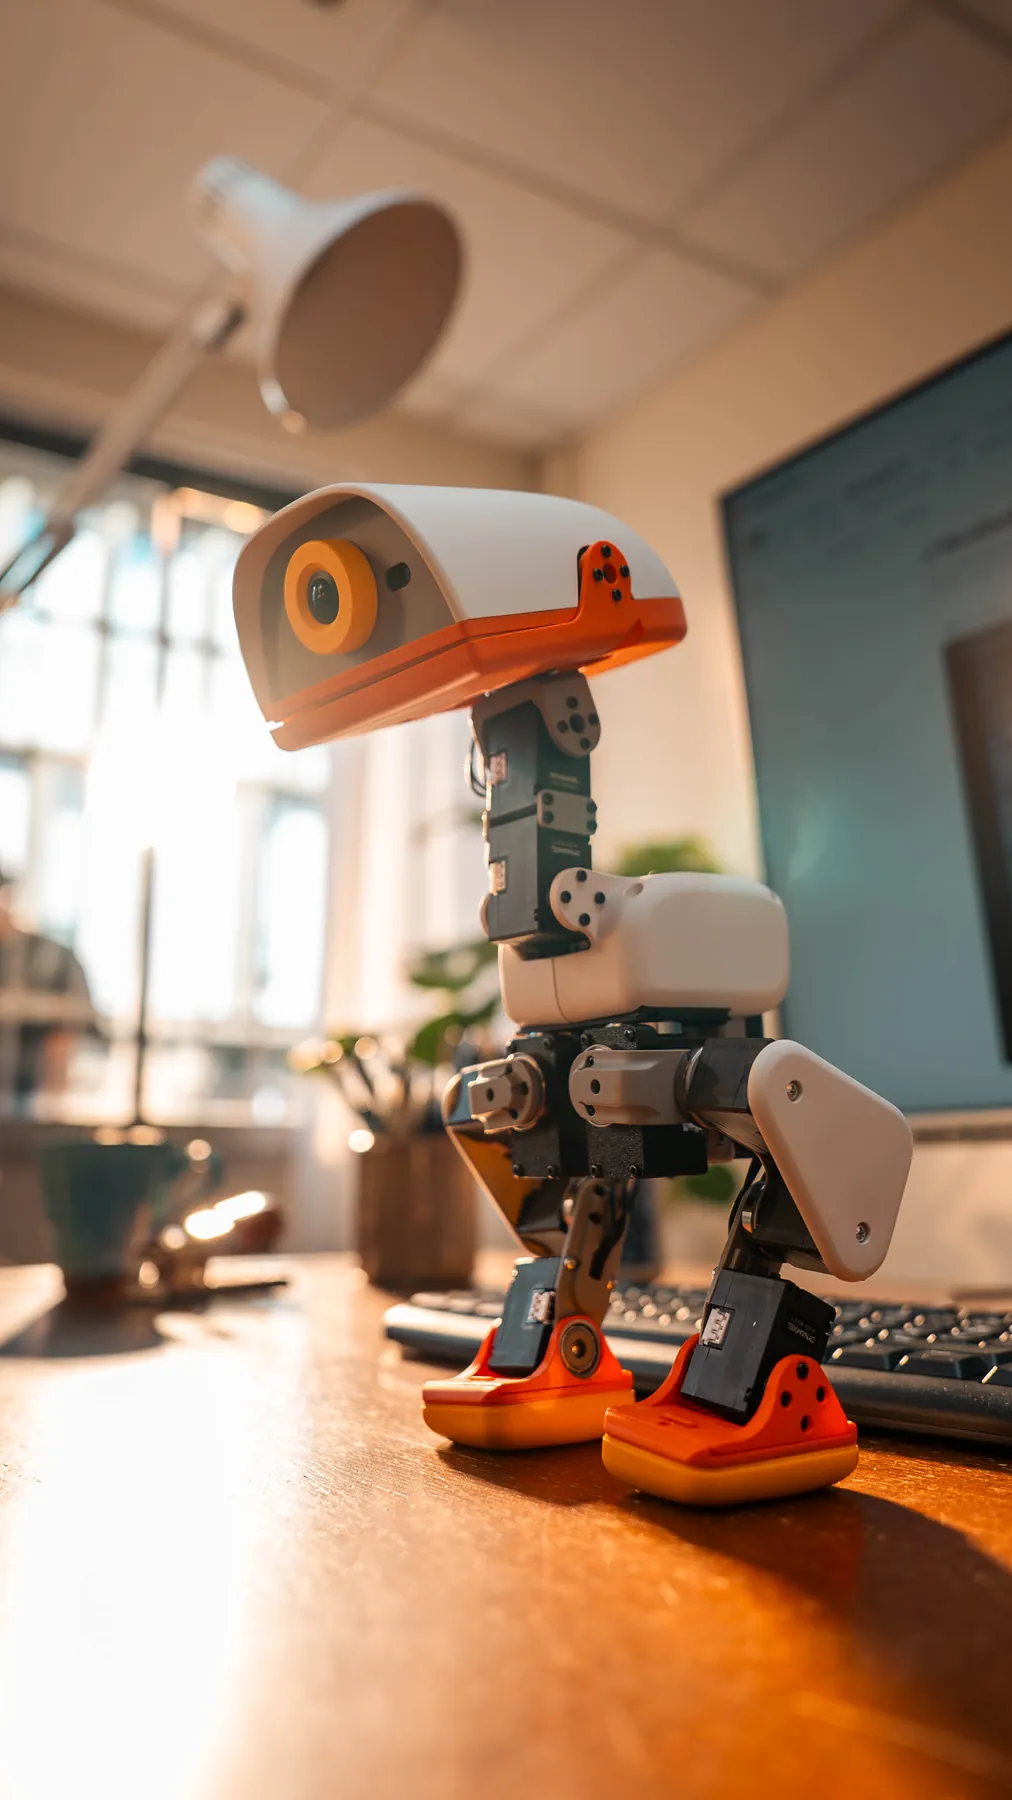
This project is currently in progress. I am building the open-source MicroDuck developed by Pollen Robotics. MicroDuck is a small 15-servo biped whose movements are generated by neural-network policies trained in simulation.
Image taken from the Pollen Robotics website.
My main goal is to become more familiar with reinforcement learning through a complete physical project: assembling and commissioning the robot, reproducing an existing locomotion policy, training a policy myself and finally transferring it from simulation to the real robot.
Why MicroDuck?
Legged locomotion is a useful reinforcement-learning problem because balance, contact and actuator limits are difficult to describe with one hand-designed controller. A policy can instead learn a relationship between the robot state, a desired motion command and the joint targets required to keep the robot stable while moving.
The project is small enough to build at home, but still includes the important parts of a modern learning-based robotics workflow: rigid-body simulation, reward design, parallel training, domain randomization, policy export, a real-time inference loop and validation on hardware.
Planned workflow
| Stage | Planned work | What I want to learn |
|---|---|---|
| 1. Build | Assemble the mechanics, electronics and servo bus; check joint directions and limits. | Understand the hardware and establish safe test procedures. |
| 2. Reproduce | Run the provided MuJoCo model and an existing walking policy. | Learn the observation, action and inference pipeline before changing it. |
| 3. Train | Train a locomotion policy with PPO and evaluate reward terms, curriculum and convergence. | Gain practical experience with reinforcement-learning experiments. |
| 4. Robustness | Randomize mass, friction, motor strength, sensor noise and latency. | Understand how domain randomization reduces the simulation-to-reality gap. |
| 5. Deploy | Export the trained network to ONNX and test it in the robot's 50 Hz control loop. | Learn safe sim-to-real deployment and hardware validation. |
First learning objective
The first policy I plan to train is commanded walking: the robot should track forward, lateral and yaw-rate commands while staying upright. I will compare policies using tracking error, episode length, energy-related penalties and robustness to moderate pushes and modelling errors.
Once the standard locomotion task works reliably, I would like to experiment with a smaller custom task or reward function rather than only running the supplied policy. Results, training curves and hardware footage will be added here as the project progresses.